Validated JSON Schema Contracts as the Missing Layer Between PDF Extraction and RAG Retrieval
Schema contracts catch extraction failures invisible to RAG systems alone.
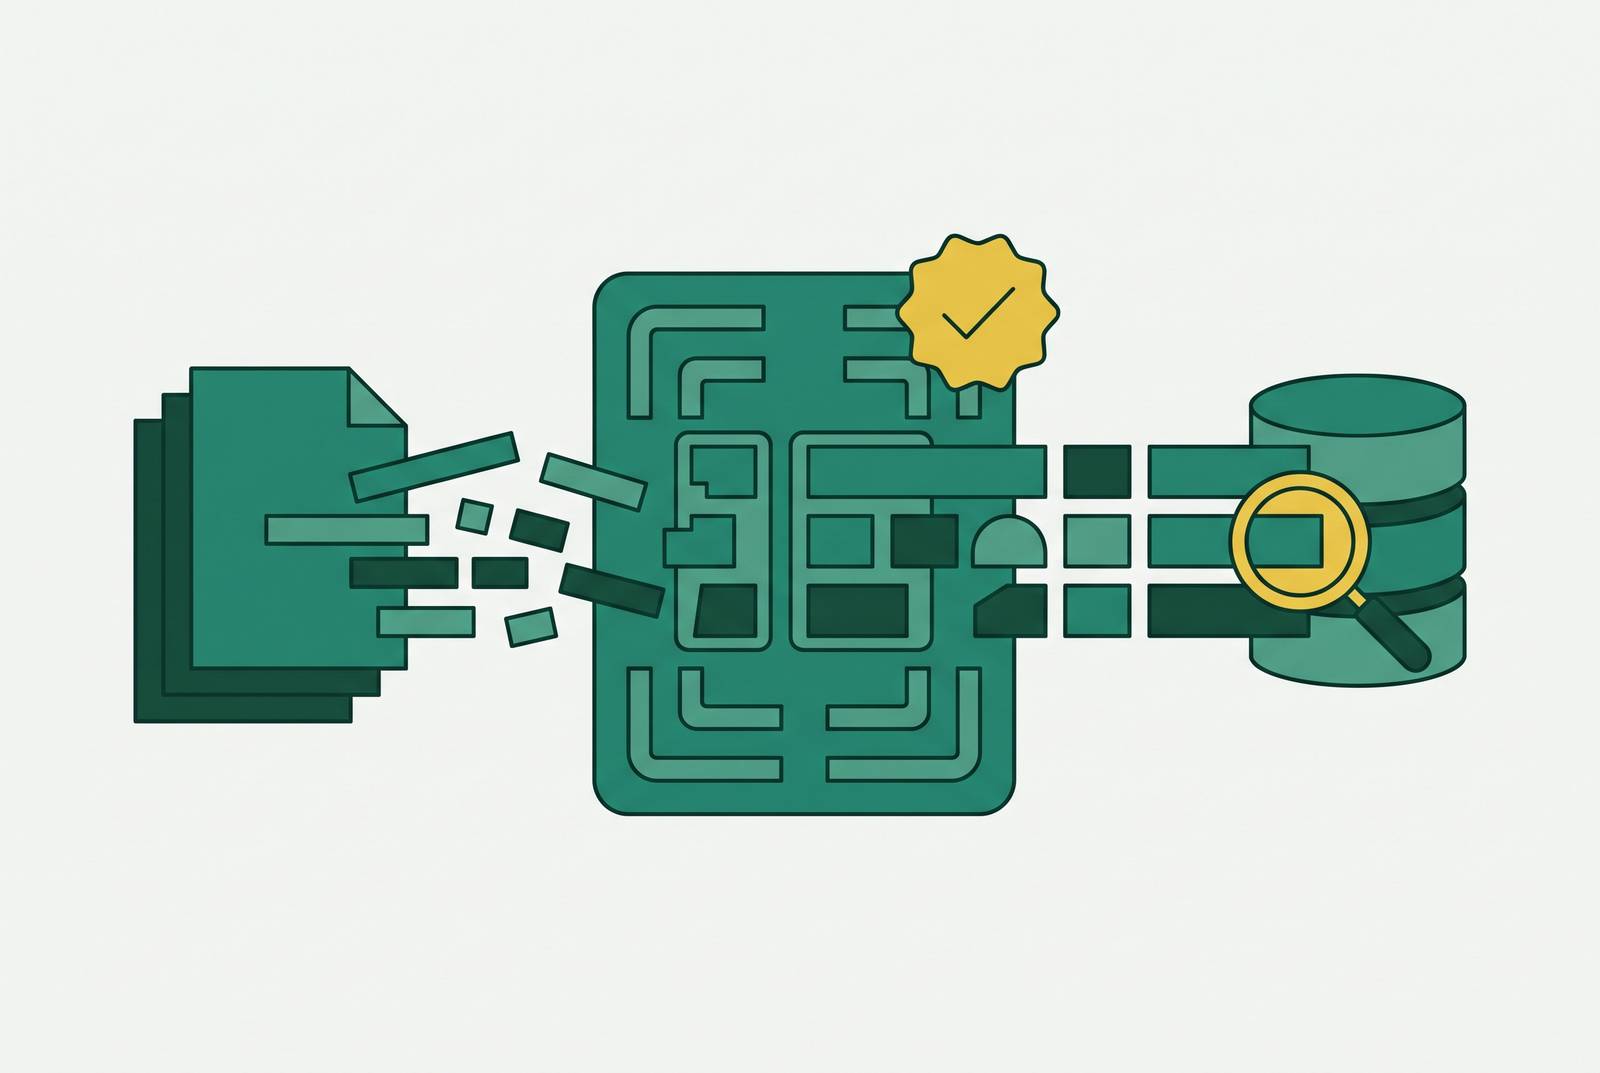
A document preprocessing API for LLM and RAG pipelines should turn PDFs into structured JSON, validate it against a declared schema, and reject or flag failures before ingestion. Validated JSON Schema contracts are the missing layer between PDF extraction and retrieval. They make structure, types, and completeness checkable, but source-grounded accuracy checks are still needed to catch plausible wrong values.
Why PDF extraction and RAG retrieval are typically treated as separate problems
A typical RAG pipeline separates offline document preparation from online answering. The offline stage parses documents, divides the content into chunks, creates embeddings, and loads them into a vector store. The online stage retrieves relevant content and uses it to generate an answer. The 2026 ICSE-SEIP study, Empirical Evaluation of PDF Parsing and Chunking for Financial Question Answering with RAG, describes this architecture and its dependency chain. The stages are separate, but their failures are not.
PDFs make that dependency difficult to manage because they are designed for people to read. Text, tables, images, and forms can coexist in layouts that resist clean extraction. If parsing drops a paragraph or scrambles a table, embedding cannot restore the lost information. Retrieval starts with what it receives. Yet teams often optimize extraction and retrieval independently, discovering the connection only after damaged content has entered the vector store.
An extractor can return output without saying whether every expected field is there, has the right type, or is complete. The retrieval system can then accept that output without knowing what was supposed to arrive. Neither stage has necessarily failed on its own terms. The pipeline has failed because those terms do not match.
How extraction fails in ways that are invisible to a RAG system without a contract layer
The most dangerous extraction failures often look like output that is right. A table can look complete even when rows, columns, or values in individual cells are missing. The financial QA study identifies misaligned tables and merged columns as examples of parsing errors that can prevent retrieval from finding the information needed for a correct answer. Those errors change the evidence available to every later query.
Wrong values can be harder to catch than missing structure. A vision-language model can transpose two digits in an invoice amount and return a perfectly plausible dollar value. The result is still a number. It may satisfy the allowed range and even survive arithmetic checks, but it does not match the document. A schema alone cannot expose that substitution, and a high model confidence score offers little protection unless it is calibrated against source-grounded correctness.
An invoice without its vendor name or a contract without its effective date leaves retrieval with incomplete evidence. Such gaps may emerge gradually as new vendor layouts, format changes, and multilingual documents accumulate. Early success can hide that slow decline. Boundary validation makes declared omissions visible, while comparison with the source remains necessary for values that are well formed but false.
What a JSON Schema contract actually does at the extraction boundary
A JSON Schema contract turns extraction into a constraint-satisfaction problem. Instead of accepting whatever structure the model generates, the pipeline declares the fields it expects, their types, their permitted formats, and whether they are required or optional. Date fields can require ISO 8601 formatting, while amount fields can have numeric bounds. The output must meet those declared conditions. Validation then happens before the data enters the vector store.
The declaration also guides the extraction model upstream. It tells the model which specific fields to find, including requested values that may exist only in visual content such as charts. Constraining the output space can reduce invented concept names, type violations, and inconsistent formatting. But prompting is not enforcement by itself. A separate deterministic step must parse the generated JSON and check it against the contract.
Post-processing may normalize values to declared types and remove unknown concept identifiers before validation. Those operations need to remain distinct from proof that the extracted values are correct. A required field that still fails validation must block ingestion or be flagged for human review under the configured policy. The contract governs both sides of the boundary. It sets out what extraction must produce and what ingestion may accept, but valid structure alone does not ensure that the content was transcribed correctly.
What the research shows about schema-constrained extraction improving RAG accuracy
MasonNLP at MEDIQA-SYNUR 2026: Retrieval-Augmented Large Language Models for Schema-Constrained Clinical Information Extraction provides evidence for combining retrieval, declared schemas, deterministic post-processing, and auditing in one extraction pipeline. Its task is converting nurse-patient transcripts into structured clinical observations. Its best configuration uses GPT-5.2 with RAG, the full schema, and a second-pass audit. The paper reports consistent gains from retrieval. It also finds that the best degree of schema constraint depends on the model.
That distinction limits what the result proves. The study does not establish a universal compounding effect from combining retrieval with schema constraints. Instead, it treats them as separate factors whose settings affect the result. A pruned candidate schema and a full schema produce different performance profiles across the tested models. Second-pass auditing adds modest gains by correcting remaining schema-adherence errors, supporting a multi-stage discipline.
The financial QA study supplies the PDF-specific connection. It finds that parsing and chunking choices interact, affecting whether retrieval can recover the information needed to answer financial questions. That supports checking extracted structure before downstream processing, but it is not a direct test of JSON Schema enforcement. Retrieval works better when its input is well prepared, and schema-constrained extraction needs to be designed and tested for each model because a larger schema cannot be assumed to be better.
Per-field accuracy measurement as the prerequisite for knowing whether a schema contract is working
Schema validation tells a team whether the output follows the rules it set. Per-field evaluation tells it whether that output matches the document. These are different tests, and both are necessary. An aggregate accuracy score can hide errors in amounts, dates, or identifiers when the model does well on easier fields. Checking against verified ground truth shows those differences before a broad claim of success hides a weakness in production.
The useful measurement unit is the individual field, segmented by document type and confidence band. Depending on the field, the measures can include precision, recall, F₁, or character and word error rates. Confidence bands reveal a particularly dangerous pattern. A field repeatedly extracted incorrectly with high confidence is not just inaccurate but poorly calibrated. Even when a value in that group is schema-conformant, the model's certainty is too little reason to trust it.
Calibration provides a basis for routing decisions. Fields that meet a calibrated confidence threshold can go through automatically, while fields with lower confidence go to human review. A distribution-free statistical guarantee requires an appropriate calibration method, a held-out calibration set, and calibration and deployment data that are exchangeable. A threshold alone provides no such guarantee. Teams therefore need to account for changes in document conditions when judging what confidence scores mean.
High-impact fields also need checks beyond schema conformance. For amounts, arithmetic checks can test whether line items sum to the stated total. Cross-document consistency checks provide another layer for amounts, dates, and tax identifiers. These checks supplement comparison against ground truth. A vendor's single accuracy percentage says nothing about which fields fail, under which document conditions, or whether its confidence scores support safe automation.
How schema contracts change the shape of extraction failures when they reach human review
A schema violation gives a reviewer a specific failure to address. Without that signal, a wrong RAG answer may look like a retrieval or generation problem, requiring manual tracing through the pipeline to locate the extraction error. Boundary validation shows which field failed as soon as the violation occurs. The search becomes smaller and more concrete. Review can focus on a missing required date or an invalid amount.
Source spans make that review useful for errors that types and formats cannot catch. Requiring a bounding box or precise text location for each extracted field gives the reviewer somewhere to compare the value with the document. A field with no locatable source should be flagged automatically. Location provides evidence, and the reviewer still needs to establish that the extracted value matches what appears there.
Corrections then have a defined place in the feedback loop. Each correction can be associated with a field, a document type, and a particular failure mode, making it more useful for retraining than an edit to free-form retrieval output. Repeated failures can identify the layouts and field types that need attention. The schema supplies a stable target for improvement.
Where schema contracts are most consequential: regulated, high-volume document workflows
Mortgage lending, healthcare, insurance, and accounts payable expose the cost of silent field errors. In mortgage lending, new GSE rules are pushing lenders toward deeper audits of vendor AI systems. Validation records and accuracy evidence for each field give those audits something specific to check. A general model accuracy claim does not. The contract makes it possible to distinguish what was required, what passed validation, and where extraction performance still needs scrutiny.
Healthcare and insurance add the risk of automated decisions that significantly affect individuals. GDPR restricts such fully automated decisions, making human intervention an important design consideration where its protections apply. Confidence-threshold routing tied to schema validation can provide a documented trigger for review. It is not, by itself, proof of compliance. The distinction also applies to explanations, which a recital discusses but does not mandate as explicitly as the right to human intervention.
Accounts payable faces a different pressure from repeated variation. Multi-invoice PDFs, multilingual documents, and vendor-specific layouts can steadily erode extraction accuracy after an apparently successful rollout. A schema for each document type keeps the target the same even as those documents vary. Review and retraining can then address failures against the same declared fields. When volumes are high, keeping that target the same helps keep small, repeated errors from being hidden by a broad measure of success.
Per-field accuracy against ground truth, field-level confidence scores, and a contractual service-level agreement make performance claims testable. Validation records establish whether the declared rules were followed. Accuracy evidence establishes how often the extracted content was right. Keeping those duties separate stops a vendor from using clean JSON as proof that it can reliably understand documents.
What to demand from any extraction API before connecting it to a RAG pipeline
For a team choosing a document preprocessing API, the first requirement is an enforced schema boundary. The API should accept or enforce a schema declaration and return conformant output or an explicit rejection. Free-form JSON that the caller must validate separately does not provide that boundary. JSON syntax is only the starting point. The service needs to enforce the required fields, types, formats, and completeness rules before its output goes into retrieval.
The next requirement is evidence at field level. Confidence scores should be calibrated, and extracted values should be traceable to source spans in the document. Aggregate model confidence or a single pass/fail flag cannot support the same review decisions. Failure handling must also be explicit. A field that violates the contract should be reported as a failure because silently dropping it or giving it a default value makes an incomplete extraction look finished.
Contractual commitments should match that level of detail. A field-level accuracy SLA covers extraction risk that structural validation cannot remove, while a broad promise of accuracy leaves the caller to find out which fields are unreliable. For regulated environments, the requirements also include zero data retention by default and documented certifications. Sensitive documents should not persist with the processing service beyond the processing event. Together, these requirements distinguish an enforceable ingestion boundary from an API that merely returns tidy-looking output.