How Google Document AI and Azure Document Intelligence Handle Production SLAs Versus Vendors That Contractually Own Accuracy
Google and Azure promise uptime, not extraction accuracy.
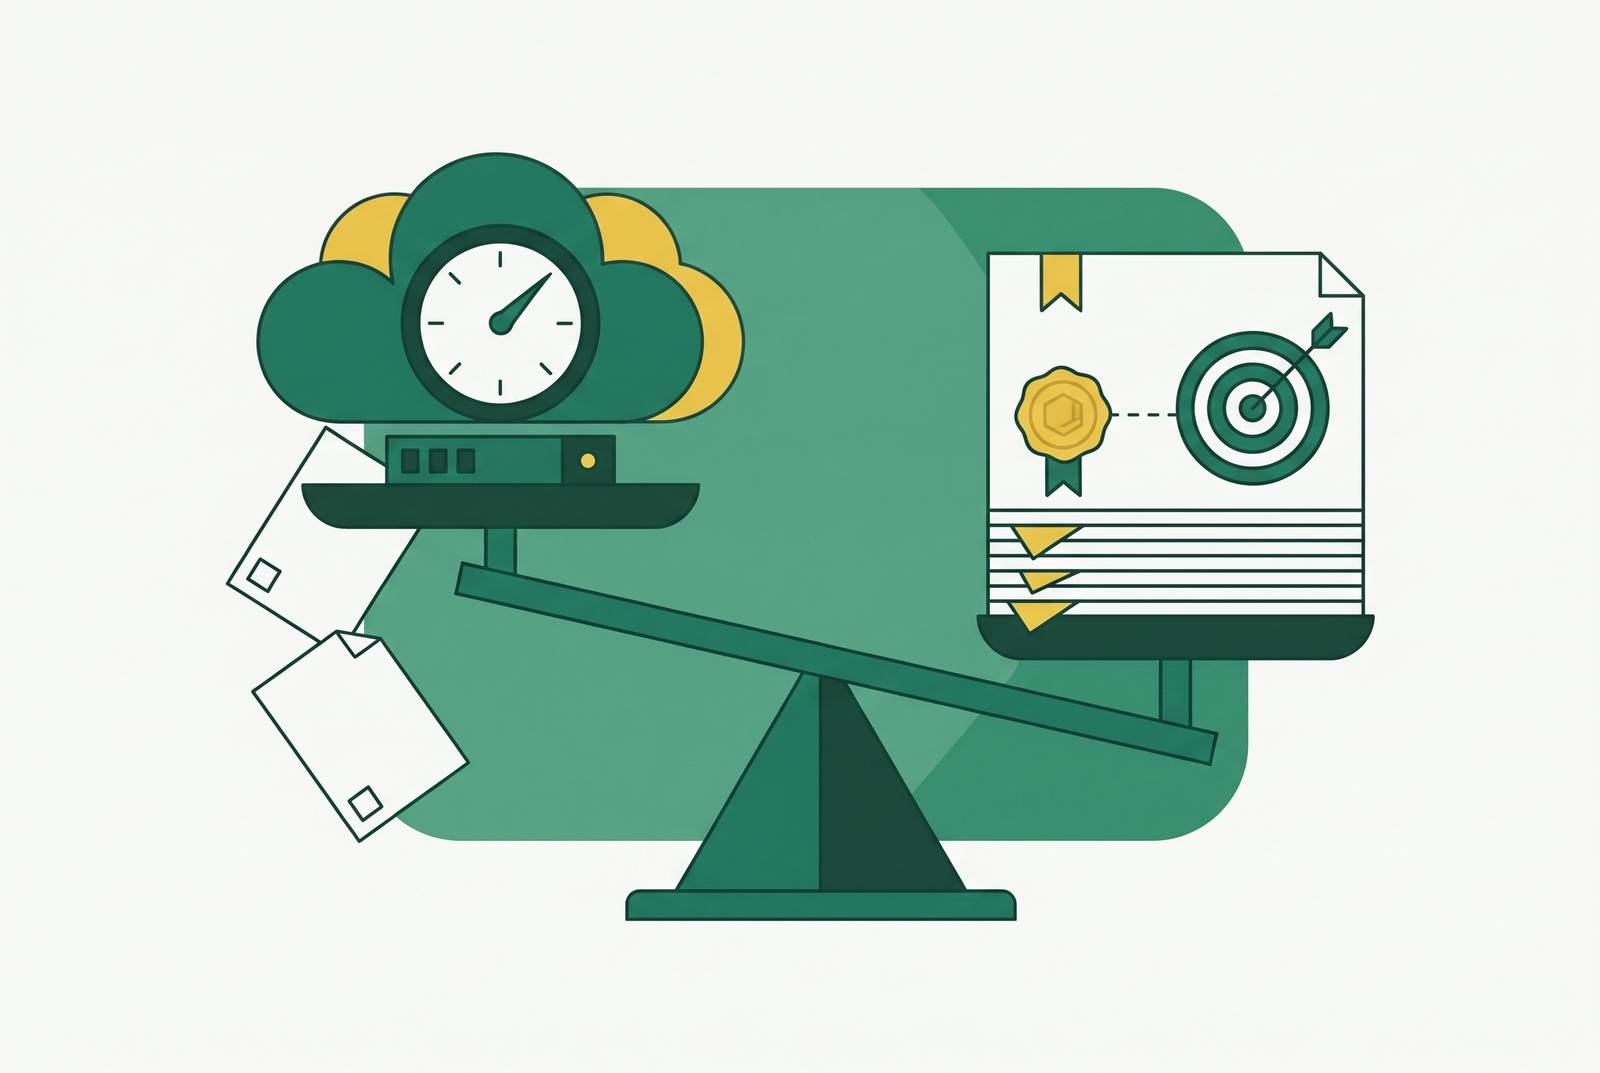
For production pipelines, the key distinction between Google Document AI, Azure Document Intelligence, and alternatives that contractually own accuracy is who pays when extraction is wrong. Neither cloud platform states in its contract how high its extraction accuracy must be. An alternative with a defined per-field accuracy SLA and remedies for missed targets changes the relationship from buying model access to buying a measurable outcome.
What Google Document AI and Azure Document Intelligence actually promise in their service agreements
Google Document AI’s service agreement commits to availability, with service credits for qualifying failures. Microsoft’s service agreement also promises uptime and service credits, but gives no promised extraction-accuracy percentage for Azure Document Intelligence. Neither agreement publishes a contractual number for correct field values. That distinction defines the scope of the purchase. The customer receives access to a document-processing service.
Availability and accuracy measure different things. A service can accept a document, process it, and return a response while extracting the wrong invoice total. A wrong field value does not, by itself, trigger an uptime SLA.
Latency, service error rates, and rate limits also concern the delivery of the service. An error reported by an API is not the same as an extraction error inside a successful response. The agreements therefore leave extraction quality outside the published accuracy commitments because there are no such commitments.
How the platforms perform in production versus what their demos suggest
Real operational documents introduce variation that curated demonstrations do not reproduce. Layouts differ between suppliers, scan quality changes, and pages mix text, tables, and other content. Those differences affect fields within the same document unequally. A clean header proves little about the table below it. Reading a vendor name or invoice number is a different task from splitting out every item, quantity, and amount correctly.
Line items make the gap especially clear. Merged cells, descriptions spread across several lines, subtotal rows inside item tables, and unusual column ordering complicate extraction. These are ordinary conditions in accounts payable workflows receiving invoices from multiple vendors. A demonstration that handles the header well can therefore leave the hardest part of the production workload largely untested.
The practical consequences include a lower accuracy figure, a review queue, threshold-tuning work, and fallback logic for documents that do not fit the expected pattern. Good results on simple fields can hide errors in the fields that decide whether a record can be used. The document may look mostly right but still need someone to fix it before it can enter the next system.
Better models can improve performance, but they do not make a controlled benchmark equivalent to an operational document population. The population being tested remains decisive. A demo shows how a platform handled the documents selected for it, while a production evaluation must show how it handles the variation the customer actually receives.
Why a confidence score is not the same as an accuracy guarantee
Confidence scores express how certain a model is about an extraction. They do not establish that the value is correct, and they do not assign responsibility when it is wrong. Both platforms provide confidence signals that teams can use in validation. Those signals are useful, but their role is limited. They help a team decide what to examine rather than relieving it of the need to examine anything.
Consider a score of 0.72 on a supplier name and the same score on a payment total. The numerical signal is identical, but the business risk is not. The engineering team must translate that difference into field-specific thresholds and validation rules.
Microsoft’s documentation describes no built-in evaluation reports such as confusion matrices, precision, recall, F1 scores, or longitudinal accuracy dashboards for custom extraction models. Its custom classification models do automatically generate precision, recall, and F1 scores after training. Classification metrics do not fill the evaluation gap for extracted values, so a team needs an external validation process against labeled ground truth.
A confidently wrong value exposes the limit of threshold-based review. If a model invents a value and assigns it high confidence, the score can suppress the human review that would have caught the error. A low-confidence result does show that the model is unsure. A contractual accuracy guarantee serves a separate purpose by defining the required outcome, how correctness is measured, and what obligation follows when the result falls short.
What the engineering team inherits when accuracy is uncontracted
Without an accuracy commitment, the deploying team owns the work needed to turn extraction output into dependable records. Google’s raw response is a Document object containing entities and other information, including pages, layout, and text. It is not a finished internal business record. The integration has to supply that structure. This means mapping entities to a schema, grouping line items, handling multi-page pagination, and deciding what to do with partial results.
Confidence filtering addresses only part of that work because some incorrect values arrive with high scores. The pipeline also needs fallback logic and a way to route exceptions into review. Line-item grouping takes more integration work when the way a table looks does not map cleanly to records that can be used. These tasks help control accuracy as well as format the output.
The obligation continues after deployment. Model updates can silently degrade a workflow by changing output distributions or confidence calibration without breaching an availability SLA. The service may keep running well while errors further down the pipeline show that the way it extracts data has changed. Detecting that shift requires validation beyond checking whether requests succeed.
Teams must track deprecation notices, test new versions before moving production traffic, and absorb the engineering cost of each transition. A replacement version is not just an infrastructure change when the application depends on the shape and quality of extracted fields.
Review, remediation, regression testing, and ongoing validation remain part of operating the pipeline. Where accuracy is uncontracted, the customer funds the permanent capability to detect and contain failures that the platform has not promised to prevent.
How contractual accuracy guarantees change the commercial structure of the relationship
A vendor that puts extraction accuracy in an SLA accepts an obligation that an availability-only agreement does not contain. An accuracy obligation changes the allocation of risk. A promise of per-field accuracy, with a defined way to measure it against ground truth, makes correct results part of what the customer buys. The contract now reaches into the result itself. Its scope and remedies determine how much responsibility actually transfers.
A “pay only for correctly extracted pages” model makes that distinction concrete. Waiving the charge for a page with incorrect extraction ties a commercial consequence directly to output quality. It does not, by itself, say who bears every downstream loss, so the pricing term and the wider accuracy obligation must not be mistaken for the same thing.
An accuracy promise also needs evidence that a customer can inspect. Field-level confidence scores tied to pixel-level provenance make it possible to trace an extracted value back to its location in the document. That trace supports verification against the source rather than relying on the model’s own estimate of certainty. A promise without a verifiable measurement method leaves the central dispute unresolved.
Continuous learning from reviewed corrections changes how the system is run compared with manual retraining from time to time. As document populations shift, those corrections can help the system improve on the exceptions it encounters. This helps sustain a contractual target at scale.
For buyers comparing alternatives, a measured target, a defined test method, traceable evidence, and an explicit consequence for failure establish what the vendor owns when claiming “high accuracy. A customer who switches providers but keeps those terms may still have to do the same work to ensure accuracy under a different API.
Why regulated and high-volume environments cannot treat accuracy as an engineering variable
In regulated workflows, an extraction mistake can become an accountability problem beyond the engineering team. Mortgage lending, for example, involves documented AI governance requirements, so an accuracy failure can become an audit finding. A review queue does not resolve that exposure by itself. The organization also needs a defensible account of how output quality is evaluated and controlled.
Healthcare creates a related pressure around critical structured documents. If field-level accuracy falls below the workflow’s acceptable floor, human quality assurance must make up the difference. At high document volumes, that dependence can undermine the economics and operating purpose of automation. A process that requires sustained manual checking is not equivalent to one that meets its accuracy requirement without that burden.
Google supports EU and other non-US regions for document storage and processing, but region selection does not remove the jurisdictional exposure associated with a US-incorporated provider under the US CLOUD Act. For EU buyers whose rules bar that exposure, regional hosting alone does not meet their sovereignty needs. That is a separate issue from whether extracted fields are correct.
Azure offers Docker container deployment for on-premises use, while Google has no matching on-premises Document AI deployment. This difference can shape which service fits a regulated environment, even before accuracy is evaluated. It does not turn a deployment option into an extraction guarantee. Location, jurisdiction, retention, and correctness each need their own terms.
For sensitive financial and personal documents, the contractual requirement should include zero data retention. A vendor assurance is not a substitute for that term. Buyers need both acceptable data-handling terms and accuracy commitments, since neither can make up for failures in the other.
How should a team evaluate an extraction platform before committing?
The practical response is to test candidates on a representative sample of actual documents before committing. An afternoon of testing against labeled ground truth is more relevant to the decision than a polished demonstration on selected examples. The sample needs to reflect the document population the pipeline will receive. Otherwise, the evaluation repeats the demo’s central weakness.
Measure correctness at the field level. A record with most fields correct can still fail its purpose when the wrong field is the total amount or tax rate. Separating header fields from line items also prevents easier extractions from masking weaker table performance.
The scoring method needs to fit the field. For strings, normalized similarity against ground truth shows differences that a binary exact-match test can hide. For numeric fields, a tolerance-based comparison distinguishes a rounding difference from a wrong value. Field-aware confidence thresholds can then support validation, but they cannot replace these measurements of correctness.
Require each vendor to explain its ground-truth method, labeled test set size, field-level results, and tracking over time. Those details show whether two accuracy claims can be compared. A number without a defined denominator and method is not enough to rank platforms. The checks should be the same for a cloud API and a vendor that offers an accuracy SLA.
Then ask whether the vendor will put its measured accuracy in the contract. For a team replacing Azure because accuracy varies and costs are unpredictable, that question separates a change of supplier from a change in commercial responsibility. For a team leaving Google to rely less on one cloud, deployment and data-handling terms must also fit where and how the team plans to run the service. Neither goal is established by an accuracy percentage alone.
For a vendor offering a per-field SLA, correct-page billing, and source-pixel traceability, the final test is specific. Does measured performance on the customer’s documents meet the workflow’s required threshold, and what happens contractually when it does not?