Document AI API Integration Complexity and Hidden Engineering Costs
Real document AI costs run 3 to 5 times the advertised API price.
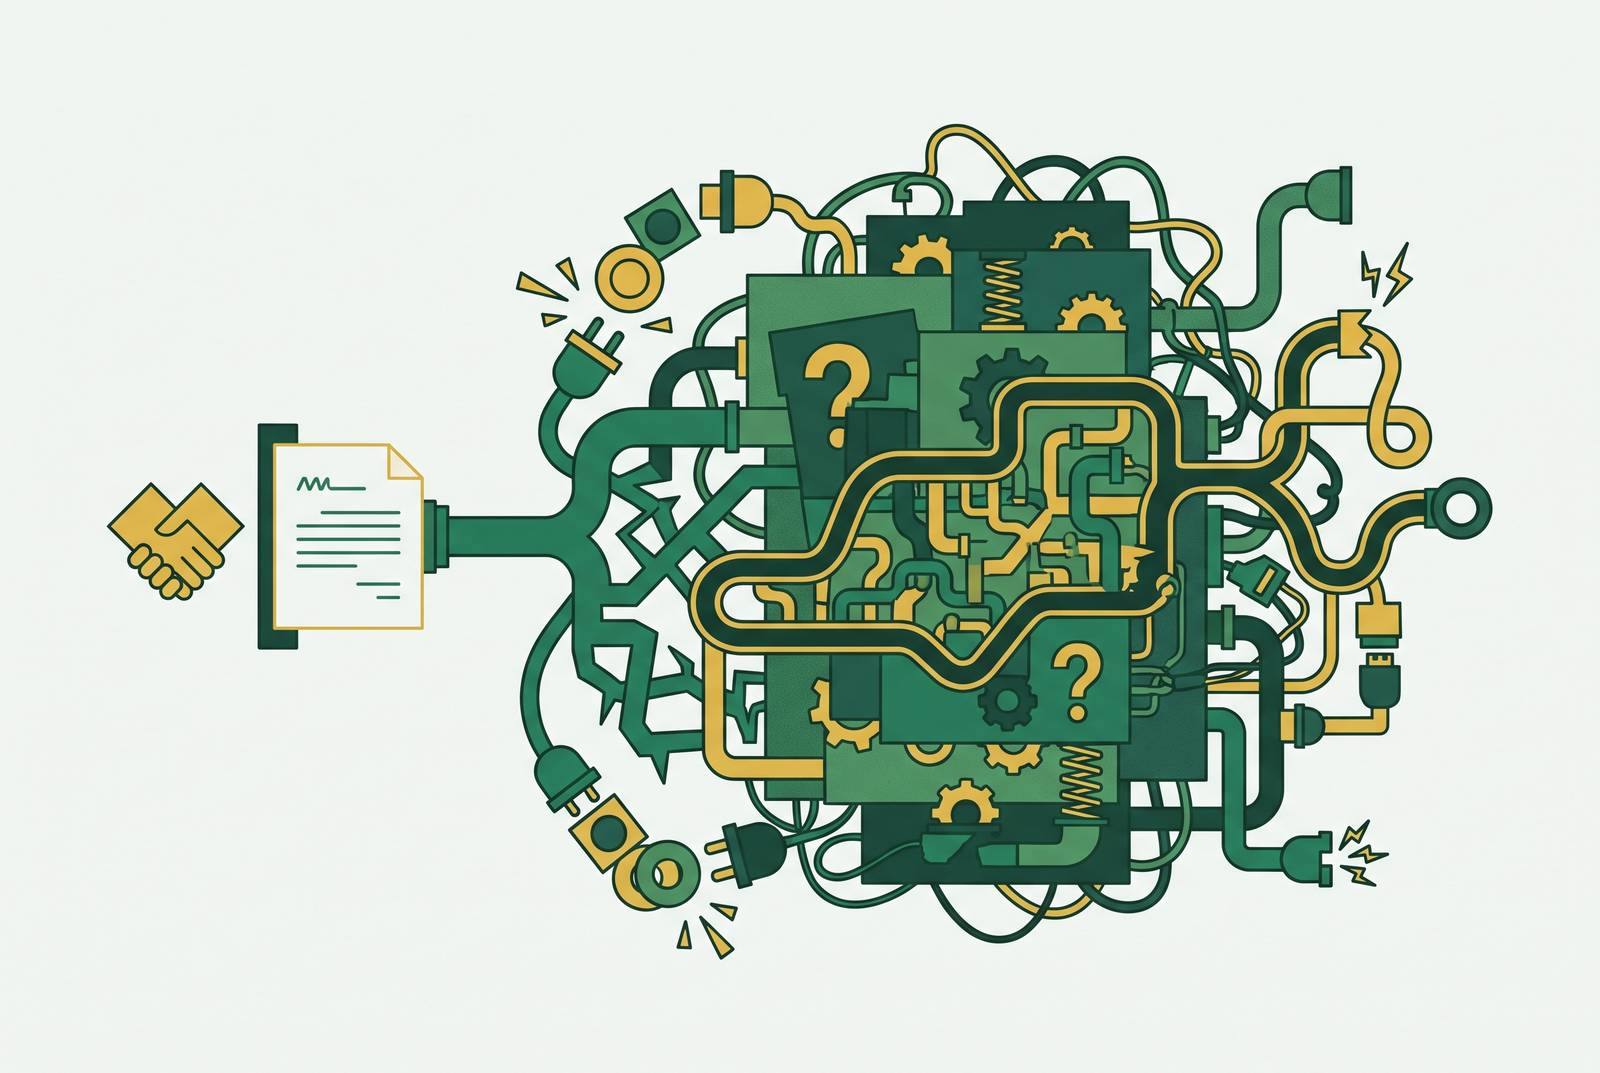
A vendor quotes you a price per page or per token, but that number is almost never what the project ends up costing. The quoted rate covers model inference: the actual act of reading a document and pulling structured data out of it. The scaffolding that turns an API call into a working pipeline gets priced separately, or it lands entirely on the buyer's own engineering team. For most teams, the real cost of running a document AI pipeline in production comes to 3 to 5 times the advertised API price, and that multiplier holds across vendors, not just one provider's pricing page. This pattern is visible industry-wide in AI adoption generally: licensing fees make up a minority slice of total cost, while data preparation, integration engineering, change management, and ongoing maintenance eat the rest of the budget. None of this means the per-page rate is dishonest. It means the rate answers a narrower question than the one a budget actually needs answered, and the sections that follow trace exactly where the rest of the cost goes.
The integration layer: what it takes to go from API call to working pipeline
Calling a document AI API and running a document AI pipeline in production are two different undertakings, and the gap between them is a small software project, not a quick integration. Most initial proposals scope the work as if it were the latter. That is where the first budget miss happens.
The integration layer has to handle authentication and credential management: service accounts, API keys, and the token refresh logic that keeps a pipeline from silently failing overnight. It has to manage document ingestion, routing files in from email, SFTP, or an upload endpoint, and getting each one into the format the API expects. It has to parse the response, translating whatever entity structure the processor returns into the schema the downstream system (an accounting platform, a loan origination system, a claims database) actually requires. It needs retry logic, circuit breakers, and rate-limit handling. Each retry resends the full payload, and each one gets billed again. At any real volume, the pipeline needs queue management and asynchronous processing to absorb spikes without falling over. And none of it is worth much without logging and observability, because a pipeline that fails silently is worse than one that fails loudly.
Google's own Document AI documentation lays out the setup sequence: create a GCP project, enable the API, create a service account, download the credentials, configure the SDK, write the processing code, handle the output. So that is seven steps before a single invoice gets processed in production, and none of them touch the model itself.
Document AI pipelines carry one more layer that generic API integrations don't: classification. Before a system can extract fields from a document, it has to know what kind of document it is looking at: an invoice, a contract, a credit memo. That classification step gets treated as free in a lot of planning conversations, but it requires its own logic, its own testing, and its own failure modes. Document AI and NLP systems occupy their own cost tier in AI project scoping, because accuracy requirements and document variety drive integration complexity more than raw volume do. Two teams can run the same API at the same page count and still end up with very different integration bills, depending on how varied their incoming documents are.
Token and context overhead and the API bill
The per-token API rate is supposed to be the fixed part of the cost, but it runs higher in practice than the pricing page implies. Document processing generates structural overhead that compounds at volume, and no engineering mistake needs to happen for that to occur.
Seven categories of hidden API cost exist beyond what a pricing page lists, and the three biggest are context window waste, retry overhead, and system prompt bloat, each one inflating the bill by a meaningful fraction on its own. For document AI pipelines specifically, three mechanisms do most of the damage. Every extraction call carries a system prompt, the instructions telling the model what to extract and how, and that prompt is billed as input tokens at the same rate as the document content itself. At scale, that tax recurs on every single call. Retry waste compounds fast too: a request that fails three times before succeeding costs four times the normal price, and at even a modest failure rate, standard retry logic pushes effective cost up materially. Tokenization adds a third wrinkle: different providers use different tokenizers, so the same document can consume noticeably more tokens on one platform than another, and that matters directly when you compare vendor pricing head to head.
Input and output pricing asymmetry compounds all of this. Input tokens are priced cheaper than output tokens across most providers. A document AI call, by its nature, sends a long system prompt plus a long document as input and gets back a short structured output: a handful of extracted fields. That's the opposite of the pattern that keeps a bill low. Cost planning for a document AI pipeline has to happen at the prompt and workflow design stage, because by the time the pipeline is in production, the billing pattern is already locked in and the only lever left is retry reduction.
None of this is a story about sloppy engineering. A team can build the integration layer correctly, write clean retry logic, and structure prompts sensibly, and still find the API bill running well above the advertised per-token rate, because the overhead is built into how document processing interacts with token-based pricing.
Validation and error handling: the engineering cost that scales with accuracy requirements
An API that returns an answer is not the same thing as a pipeline that returns a verified answer, and the gap between those two is where engineering cost concentrates hardest.
Trusting extraction output requires evaluating field-level confidence scores, not just confirming that a document processed successfully, but checking whether each individual extracted field clears the threshold its downstream use demands. Those thresholds can't be uniform across document types. An invoice carries a different baseline difficulty than a contract, so if you set one global confidence threshold, you get false positives in the easy cases and false negatives in the hard ones. Fields that fall below threshold need somewhere to go. That means building and maintaining a human review queue, a review interface, and an audit trail behind it, none of which is a small undertaking.
Confidence scores themselves carry a trust problem. Research into AI API hidden costs and newer work on confidence meta-modeling both confirm that stated confidence scores can be unreliable: a high-confidence score from a vision model can still reflect a hallucinated value, untethered to actual content on the page. So per-field accuracy is the metric that matters, not document-level accuracy. A model can score well in aggregate while carrying a much higher error rate on the specific fields, amounts, dates, tax identifiers, that carry the most downstream consequence when they're wrong.
Production systems also run into a long tail of edge cases that initial testing never surfaces: multi-column layouts, merged table cells, information that continues across pages, scanned documents with poor resolution, handwritten annotations. Each one needs its own handling path. The architecture that holds up under this pressure tends to be hybrid and multi-pass: different extraction approaches depending on document characteristics, separate representations for embedding versus extraction, and verification passes built to catch and correct what the first pass got wrong. Each piece adds engineering scope on top of the last.
The stakes here are concrete. Accenture processes over half a million client-facing invoices a year, and in an early iteration, up to 30% of invoice requests failed to process correctly because of template incompatibilities. That failure rate occurs only when real document variation hits a pipeline at volume, so pre-launch cost estimates miss it.
Maintenance as a permanent operating cost, not a one-time setup fee
Everything built in the validation layer has to keep working as the documents flowing into it keep changing, which makes maintenance a cost recurring every year.
A document AI integration doesn't settle into a stable state after it goes live. It keeps moving as upstream systems change, document formats drift, and the extraction models behind the API get updated. Annual AI maintenance tends to run as a substantial recurring percentage of the original build cost, and in many production AI systems, the cumulative operating cost overtakes that build cost in 18 to 24 months.
Document AI pipelines have their own specific maintenance drivers. Format drift is constant: suppliers redesign invoice layouts, governments update tax form templates, banks revise statement formats, and each change can break extraction logic that worked perfectly on the previous version. Model updates compound the problem: when a provider updates its underlying model, extraction behavior can shift without any version bump to flag it, so outputs that passed validation last month can start failing this month. Confidence thresholds need recalibration as the document mix evolves, because a threshold correct at launch can drift out of alignment as the inputs change around it. And edge cases keep accumulating: production systems surface new failure modes continuously, and each one needs diagnosis, a fix, and regression testing before it's actually resolved.
A banking institution that budgeted a fixed amount for integrating a credit risk AI system found the real number instead: a 126% overrun on the integration budget, driven by missing APIs, scattered customer data, and undocumented systems. That gap reflects a structural feature of integrating AI into real legacy environments, where the systems on the other end of the pipeline are rarely as clean as the architecture diagram suggests.
Broader cost analysis of AI software development backs this up, naming model retraining and drift management, monitoring infrastructure, and compliance maintenance as distinct budget lines that most proposals leave out entirely, each one applying directly to document AI pipelines operating in regulated environments. None of this argues that maintenance can be avoided. It argues that maintenance is predictable enough to price honestly from the start, which gives a team the information it needs to decide rationally whether to own that cost directly or transfer it to a vendor built to absorb it.
Compliance overhead in regulated document workflows
In lending, insurance, healthcare, and accounts payable, which are exactly the industries where document AI delivers the most value, compliance isn't an add-on bolted to the pipeline afterward. It shapes every architectural decision from the start, and it adds cost at every layer it touches.
The compliance stack relevant to document AI in 2026 spans several frameworks at once. SOC 2 Type II is the baseline expectation for any B2B vendor handling customer data. GDPR applies, and the EU AI Act, a distinct regulation, now sits alongside it with AI-specific obligations, and its enforcement powers apply from August 2026. HIPAA governs healthcare document workflows specifically. ISO 27001 rounds out the set. In a regulated industry, SOC 2 certification alone rarely satisfies the full compliance requirement.
Data residency often decides vendor selection outright in these industries. A pipeline where extracted content, PHI, PII, financial account details, touches a vendor's infrastructure creates third-party compliance risk that has to be scoped, assessed, and written into a contract before anything goes live. Zero data retention follows from that same pressure: it isn't a nice-to-have feature but an architectural requirement for pipelines handling sensitive documents. A platform that processes a document and purges it immediately, never storing it, never using it for training, shrinks the compliance surface considerably compared to one that doesn't.
Compliance and regulatory requirements rank among the six real drivers of AI software development cost, and regulated sectors consistently pay more and take longer to deploy as a result. The audit, the legal review, and the certification work required before a document AI pipeline can touch live financial or health data don't sit off to the side of the budget as a formality. It's a budget line of its own, and the stakes behind getting it wrong are concrete: HIPAA penalties reach up to $1.5 million per violation in 2026.
This is where zero-retention architecture and SOC 2, GDPR, and ISO 27001 certification stop working as compliance checkboxes, and start working as engineering decisions that cost you directly. A vendor that has already built and absorbed that infrastructure transfers the cost off the buyer's plate. A vendor that hasn't leaves the buyer with two options: build that infrastructure in-house, or accept the compliance gap and the risk that comes with it.
Where build-vs-buy decisions go wrong in document AI
Every cost layer covered so far, integration, API overhead, validation, maintenance, compliance, converges on the decision most engineering teams actually have to make: build a document parsing pipeline in-house, or buy a platform built for the job. Regulated industries feel this decision most acutely, because compliance failure there costs the most.
Teams that choose to build in-house tend to underestimate total cost because they scope only the model layer and treat everything else, validation, maintenance, compliance, as an implementation detail to handle later. The true scope of an in-house build includes OCR engine selection and ongoing maintenance, layout analysis and table extraction tuning, annotation pipelines and labeled dataset management, exception handling interfaces and queue management, confidence calibration tuned per document type, and continuous monitoring and retraining. Most of that list never appears as a line item in an initial build proposal. That is why in-house projects run over budget in the same places, over and over, regardless of team or industry.
Buying a production-grade document AI platform means inheriting work that already exists: years of R&D, pre-trained models built for specific document types, compliance infrastructure already in place across SOC 2, GDPR, and ISO 27001, and integration libraries ready to plug into an existing stack. If an in-house team started from zero, it would need 12 to 18 months to build toward that same level of capability before it reached comparable ground.
Neither path is free, and neither is automatically wrong for you. If you use the per-page price as the reference point, you make the build-vs-buy decision on incomplete information. The one made with integration, overhead, validation, maintenance, and compliance costs priced in from the start is the one that holds up once the pipeline is actually running at volume.