Eliminating Garbage-In at the Document Ingestion Layer Before It Reaches Your LLM
Clean data at ingestion prevents hallucinations that prompt engineering alone cannot fix.
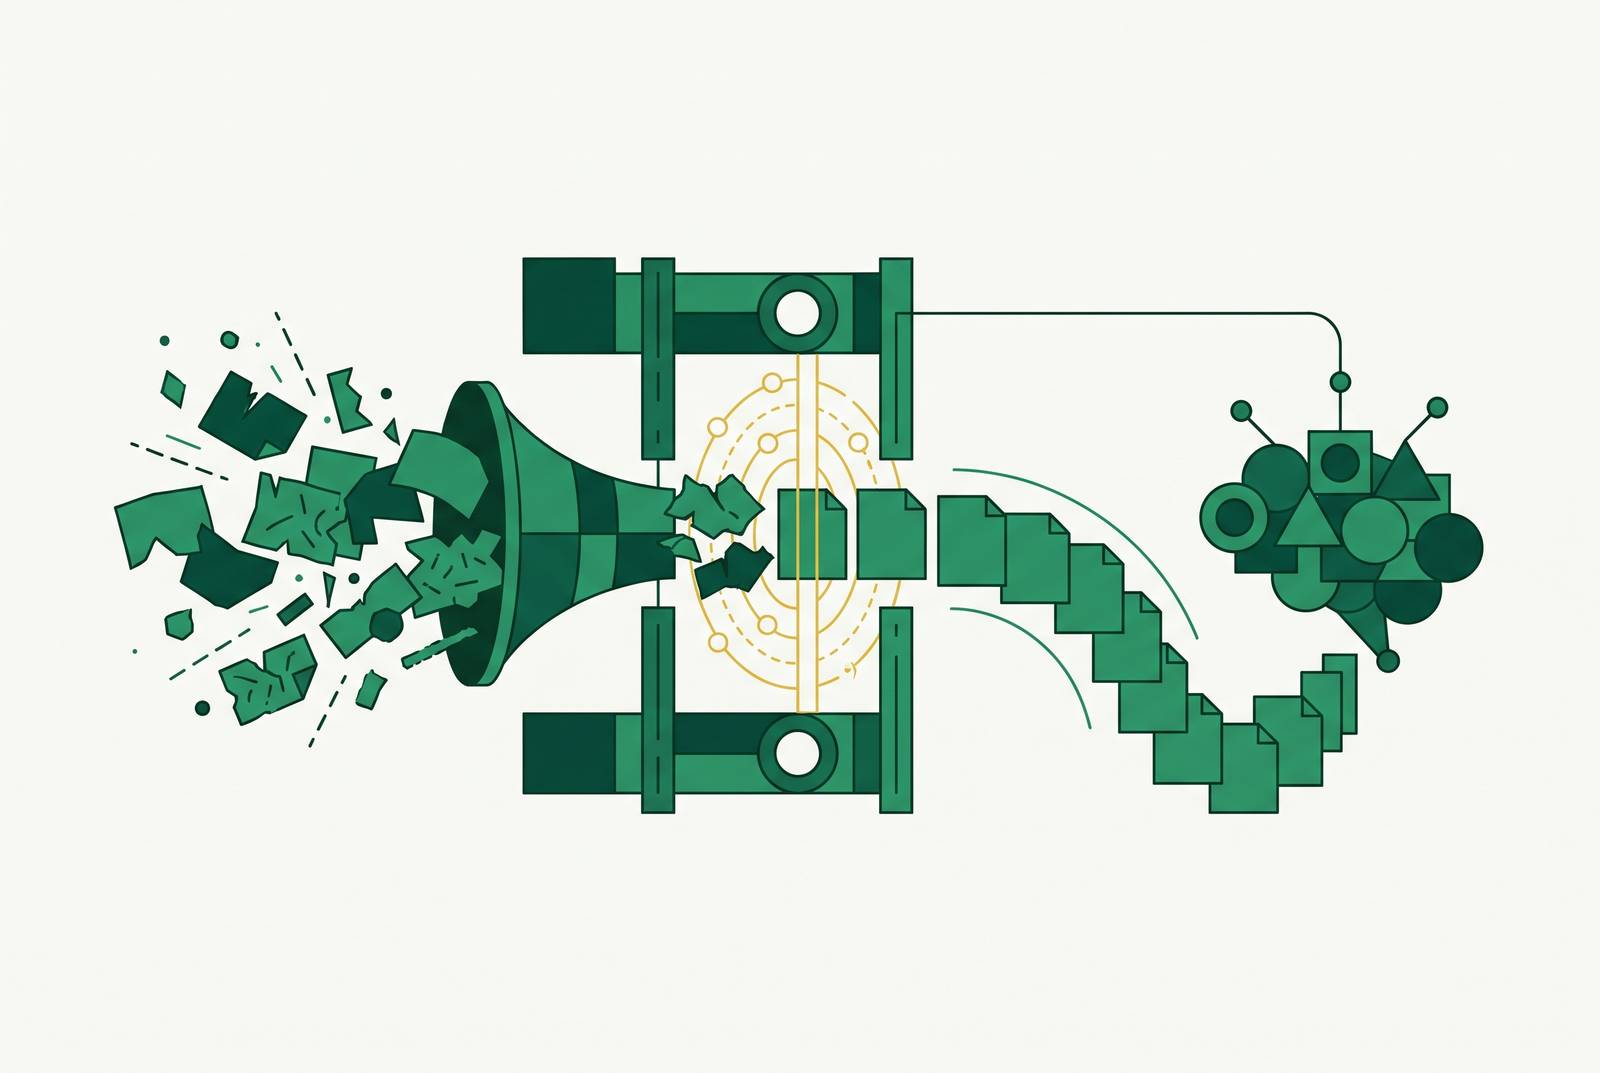
A document preprocessing API for LLM and RAG pipelines should deliver validated structured JSON. For input to be clean before it reaches the downstream model, it needs separate checks of the page and its text, grounded field-level confidence, semantic validation, and zero-trust parsing. Invofox is one option for this architecture. The engineering priority is to stop document corruption at ingestion rather than ask a prompt to repair evidence the model never received.
Why LLM hallucinations are an ingestion problem, not a model problem
A table looks correct on the PDF page, but extraction breaks the relationship between its rows and columns. The model gets the broken table and bases its answer on links that differ from those a human sees. Its answer sounds confident because the corrupted context gives it no reason to doubt the input. Changing the prompt cannot put the table back into its original structure.
This is an ingestion failure that can look like a reasoning failure. It identifies a class of errors that model changes cannot repair at the source. Malformed, incomplete, or semantically substituted text can produce an answer that follows the supplied evidence and still contradicts the document. The relevant engineering discipline is therefore semantic integrity. It means preserving what the document says before asking a model to reason about it.
The four families of extraction gaps that corrupt model context
PDF rendering and text extraction are separate operations, so a document can carry two different semantic views. One appears on the page, while the other enters the model’s context. Liu and Ming (2026) instantiated 25 confirmed extraction gaps across four families by examining specification-permitted or implementation-tolerated divergence points in ISO 32000.
Semantic overrides occur when an extractor returns text whose meaning differs from the rendered page, without requiring hidden content. Hidden semantic injection instead introduces content that the human reader cannot see but the extractor returns. Reading-order splits reassemble page content in the wrong sequence, breaking an argument or a table’s relationships. Font-decoding splits arise when non-standard or embedded font mappings decode differently from their visible glyphs. These are distinct failure mechanisms, so a filter for invisible text cannot cover them all.
Structured extraction adds another layer of failure after the page has been read. Prompt-only JSON extraction can return current_state where the schema requires status, silently omit required fields, or substitute strings for numbers. These failures corrupt the contract between extraction and the software that consumes it. A valid reading of the page can still become an invalid record, just as a well-formed record can contain a bad reading of the page.
Why the ingestion stack — not the model — determines what corruption reaches reasoning
Liu and Ming (2026) evaluated the gaps across 16 PDF processing stacks and 7 commercial LLM services. Every evaluated service was exposed to at least some gaps, with exposure driven primarily by the ingestion stack. For the same nominal model, APIs, cloud backends, web frontends, and local runtimes could expose different views of the same PDF. The route into the model determines which representation it receives.
Downstream prompt engineering still helps specify the task, constrain the answer, and direct how supplied evidence should be used. Retrieval-time filtering helps select relevant content from what has been indexed. Neither approach, however, can reliably reconstruct a table relationship or missing passage that extraction already destroyed. Output validation can reject a bad response format without detecting that a schema-valid value contradicts the page. These methods remain useful, but they operate after the corruption has entered the pipeline.
Printed text with handwritten annotations, or structured tables with freeform prose, requires multiple processing paths and a careful merge. A single-path stack can leave content out, including in legal and medical workflows where that omission matters. The practical control is observability of the intermediate text or markdown. Engineers need to inspect what the model actually received.
Separating visual rendering from text-layer parsing as the first control
The first control treats the rendered page and extracted text as independent signals. Render the page to a pixel-level image, extract its text separately, and compare their meanings before accepting the result. This removes the assumption that a successful text extraction faithfully represents the page. A reconciliation step can then flag disagreement.
Liu and Ming (2026) describe dual-view consistency checking as a defense to work toward over the longer term. Their static screening scanner uses rules that trigger on all 25 benchmark gaps, providing a separate way to screen for known divergence mechanisms. That benchmark coverage is not a guarantee that every possible extraction error will be caught. Screening finds constructions that look suspicious, while dual-view comparison checks whether the two views agree. Both need to do more than filter hidden text, because semantic overrides and reading-order splits can occur without hidden payload text.
Invofox keeps visual processing separate from text-layer parsing and uses native PDF extraction with vision-model fallback for content that is scanned or hard to read from its appearance. It also offers configurable zero retention, which governs what remains after processing. For a clean-input architecture, the important extraction result is a reconciled representation with disputed fields flagged. Those flags give the next stage something concrete to assess instead of passing an unresolved disagreement to the reasoning model.
Confidence-scored extraction and grounding as the second control
Once a field has been extracted, confidence needs an anchor. A high score without a source location is not enough to show that the value came from the page. A model can be confident about a value it invented, so its self-assessment cannot substitute for evidence. Grounding ties the field to a page index, bounding box, or pixel region. That connection makes the extraction auditable.
Grounding is strongly discriminative of correctness, but it is not itself a guarantee that a field is right. The signal combines the extracted value, the region that supports it, and confidence calibrated against labeled ground truth. Review thresholds should be based on that evidence instead of how well a vendor did on sets of clean documents. Fields below the threshold should go to human review before reaching the downstream model. The source location should travel with the value so consumers can inspect the evidence without rerunning the parser.
Tools that validate outputs against a schema and expose source-traceable field scores, such as Invofox, make this intermediate layer measurable. Its per-field SLA measures how often values match ground truth, while field-level confidence is calibrated to pixel-level evidence instead of being inferred from the model’s output as a whole. A score for the whole document can hide a wrong total or date when the rest of the extraction is correct. Even a grounded, high-confidence field, however, still needs to agree with the rest of the document.
Agentic validation as the third control — catching what extraction confidence misses
Confidence asks whether an extraction is supported by evidence. Semantic validation checks whether the values that were extracted make sense together. A field can pass the first test and fail the second. Agentic validation places cross-field checks, schema enforcement, and domain rules between extraction and downstream model ingestion.
An invoice total must equal the sum of its line items under the applicable document rule. Date fields must be in the order that the rules require, and tax identifiers must pass checksum validation. These checks can expose a confidently extracted value that conflicts with other fields. They also distinguish a readable record from a usable one. A model’s certainty about the characters on the page cannot evaluate all the relationships that make the record coherent.
Schema enforcement covers a different part of that contract. Constrained decoding can guarantee schema-valid output during generation by masking invalid tokens, but it does not guarantee document-level semantic consistency. Required fields that are missing should trigger a flag or re-extraction rather than disappear silently or pass downstream as unexplained nulls. Failures at this stage should lead to re-extraction or human review before the record is accepted. Corrections from validation can then feed back into the extraction model, narrowing the gap between clean-demo accuracy and production accuracy over time.
Zero-trust parsing and the security surface the ingestion layer opens
The same boundary that creates accuracy failures also creates an attack surface. Hidden text can reach an LLM-based extractor as instruction-like content even when the page appears harmless to a reviewer. That content can attempt to override instructions or corrupt structured output. Treating the text layer as an authoritative copy of the visible page therefore creates a security weakness. The system must tell evidence in the document apart from instructions aimed at the processor.
Liu and Ming (2026) identify hidden semantic injection as one of the four gap families and show that tested safety filters cover only selected hidden-text constructions. Their findings support screening documents before admitting them to extraction, rather than relying on the final model to notice a hostile input. With zero-trust parsing, the same validation controls apply to uploads from inside and outside the organization. The document’s source does not remove the need to inspect how it renders and extracts.
With zero retention configured, intermediate representations do not remain after processing, reducing the retained-data exposure from that transaction. Invofox retains processed documents and extracted data for a defined period by default, so zero retention must be explicitly selected. GDPR Article 25 addresses data protection by design and by default, while SOC 2 Trust Criteria CC6.1 addresses logical access security over protected information assets. These requirements reinforce building security into the architecture, but parsing and retention controls alone do not establish compliance.
What API should clean and structure PDFs before they enter a RAG pipeline
A production-grade clean input layer combines these controls into a chain of acceptance decisions. Static gap screening first rejects or flags documents with detectable render/extract divergence. Independent visual and text processing then produces representations that can be reconciled, with disagreements made explicit. Grounded field-level confidence determines which extractions can proceed and which need review. The resulting record must then pass schema, cross-field, and completeness validation to be fit for downstream use.
The handoff is validated structured JSON. Source references stay with fields that are accepted, while values that are rejected or uncertain go back for re-extraction or human review. A configured zero-retention policy governs the intermediate representations after processing. Observability and retention are separate decisions, so making the processing path inspectable does not require treating intermediates as permanent records. Each stage has a defined responsibility, and no stage’s success excuses skipping the next.
The build-versus-buy decision depends on what it takes to maintain that whole chain. A custom stack requires a gap scanner, dual-path reconciliation, confidence calibration, validation rules, and retention controls. Mixed handwritten and printed content, multi-invoice PDFs, and non-standard font embeddings make those responsibilities harder once the clean demo corpus is exhausted. Comparing APIs on text extraction alone leaves out the work of maintaining that chain. The useful criteria are structural fidelity, grounded field scores, semantic checks, observable intermediate output, and explicit retention behavior.
For teams buying this layer, Invofox provides a document intelligence API that implements this architecture. Developers POST a document, receive a documentId, and retrieve validated structured JSON with per-field confidence scores asynchronously through a webhook or polling. Its commercial commitment is to charge only for pages extracted correctly, tying the service to extraction accuracy. The downstream benefit is the same whether the layer is built or bought. The LLM receives structured, validated, schema-conformant evidence that reflects the page, rather than being asked to reason its way out of corruption introduced upstream.